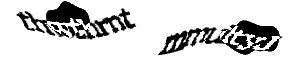
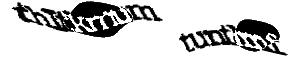In the ever-evolving landscape of digital security, the humble CAPTCHA (Completely Automated Public Turing test to tell Computers and Humans Apart) stands as a stalwart defender against the incursion of automated bots and malicious activities. But what are the origins of text CAPTCHA, the ubiquitous challenge-response system that has become synonymous with online verification? Let's embark on a journey through time to unravel the intriguing tale of its inception.
The story of text CAPTCHA begins in the early 2000s, a time when the internet was rapidly expanding, and with it, the need for robust security measures to protect against automated bots and spam. It was during this era that researchers Luis von Ahn, Ben Maurer, Colin McMillen, David Abraham, and Manuel Blum at Carnegie Mellon University embarked on a quest to tackle a pressing problem: the digitization of books.
As the digital revolution unfolded, there was a growing demand to digitize vast repositories of printed text, ranging from books and manuscripts to historical documents and archival materials. Optical character recognition (OCR) technology had made significant strides in converting scanned images of text into editable text, but it wasn't infallible. Certain words, especially those from older or damaged texts, remained resistant to OCR software's attempts to decipher them accurately.
Recognizing the limitations of OCR technology, von Ahn and his team saw an opportunity to harness the power of human intelligence to overcome this obstacle. They devised a novel solution that would not only verify human users but also help digitize books in the process. Thus, the concept of CAPTCHA was born.
The premise was simple yet ingenious: users would be presented with a challenge consisting of two words, one known and one unknown. The known word served as a verification of the user's humanity, while the unknown word was a word that OCR software had failed to recognize accurately. By having multiple users verify the unknown word, a consensus could be established on its correct transcription, effectively crowdsourcing the digitization process.
This early incarnation of CAPTCHA, known as text CAPTCHA, marked a significant milestone in the intersection of security and human-computer interaction. It transformed what could have been a vulnerability (the inability of OCR software to recognize certain words) into a strength (harnessing human intelligence to improve OCR accuracy).

In 2009, Google acquired reCAPTCHA, the commercial version of CAPTCHA, from the original developers, further solidifying its role as a cornerstone of online security. Over the years, text CAPTCHA has evolved and diversified, incorporating new challenges and verification methods to adapt to changing threats and user needs.
Its origins as a tool for digitizing books underscore the power of human collaboration and innovation in solving complex problems in the digital age. As we look to the future, text CAPTCHA remains a testament to the enduring ingenuity of the human spirit in the face of technological challenges.